Failure prevention
Detect drift early and prevent failures before they disrupt workloads.
AI cluster reliability, automated.
Autonomous failure prevention, self-healing, and incident knowledge - fully on-premise.
Why ClusterBeacon
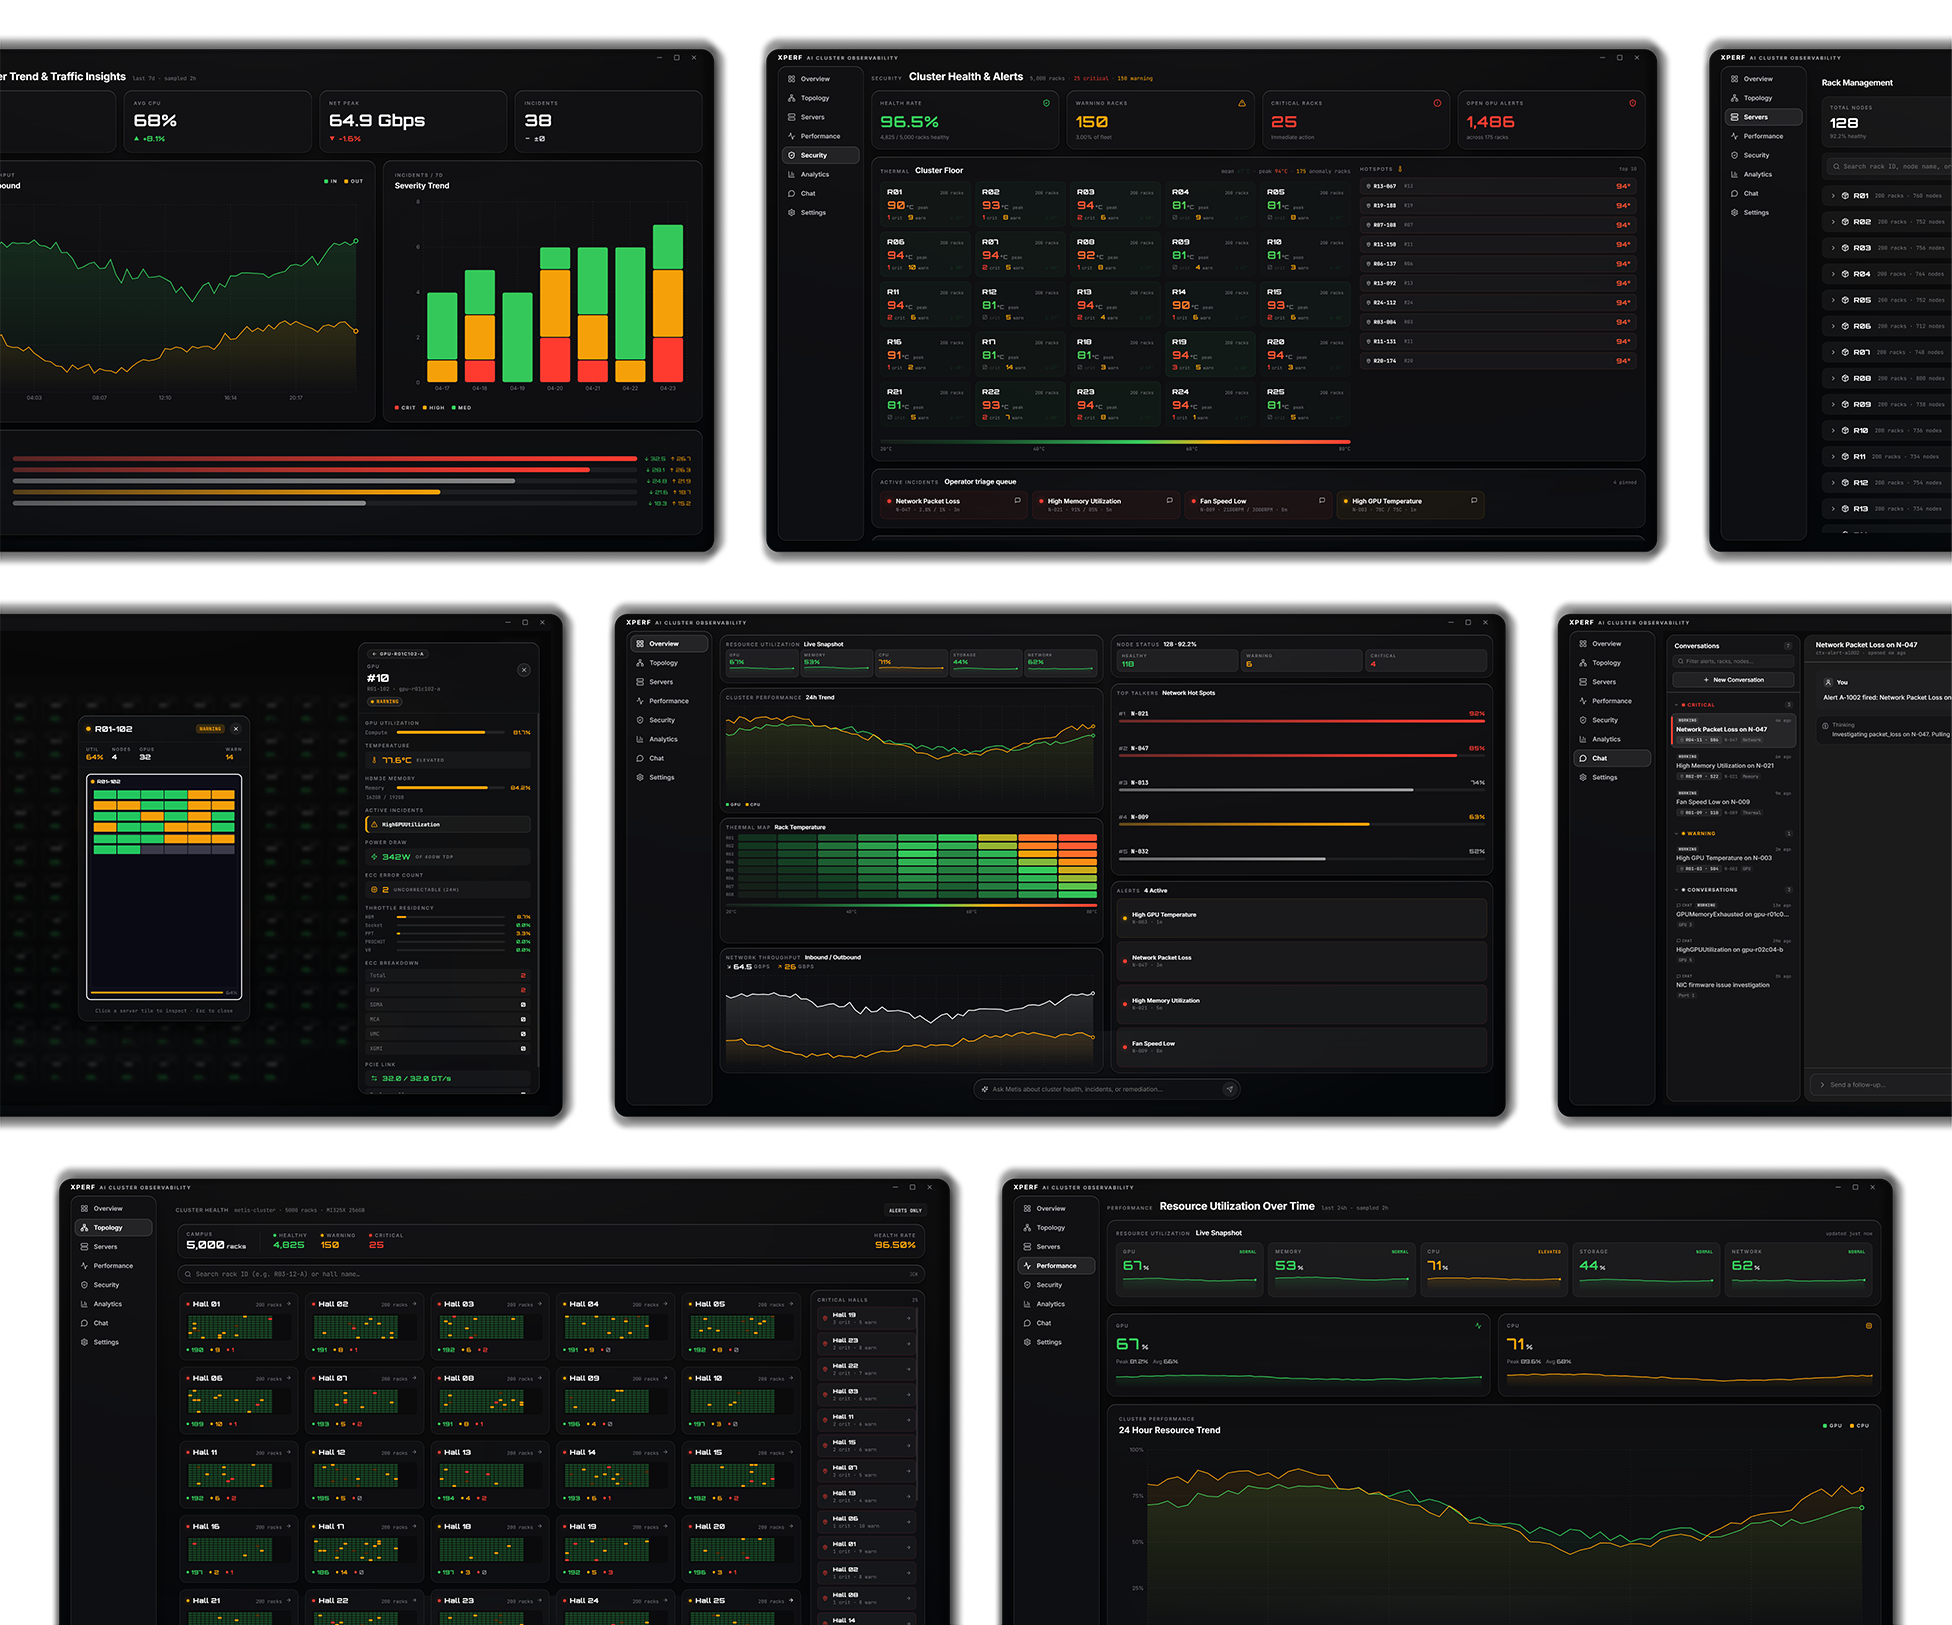
AI clusters need more than alerts. ClusterBeacon predicts failures, diagnoses root causes, and coordinates self-healing operations on-premise.
Detect drift early and prevent failures before they disrupt workloads.
Trigger proven remediation when ClusterBeacon detects an issue.
Turn every resolved incident into a reusable operational record.
Operations at scale
Autonomous prevention, diagnosis, and self-healing give infrastructure teams a 100×-1000× efficiency gain.
How it works
Four connected stages turn continuous telemetry into reliable, reviewable operations.
Learn healthy behavior across the cluster.
Create safe operating boundaries for each node.
Track health, performance, and incidents in real time.
Catch drift before it becomes an outage.
Use telemetry and incident history to find the cause.
Surface the remediation path quickly.
Apply approved fixes without losing operator control.
Keep incidents from becoming recurring work.
What ClusterBeacon watches
ClusterBeacon brings every operational signal together so teams can prevent downtime and learn from every incident.
GPU, memory, network, storage, thermal, and power signals.
Cluster health, capacity, utilization, and workload behavior.
Root causes, successful fixes, and operating context from past events.
Why teams choose ClusterBeacon
Failure prevention, self-healing, and incident knowledge for heterogeneous AI clusters.
Deployment
Runs alongside the cluster it protects.
Available as a managed SaaS option for teams that prefer cloud operations.
Get started
ClusterBeacon is onboarding select GPU operators ahead of general availability.
For GPU operators running AI infrastructure at scale.
[ Request early access ]Deploy within your facility, including air-gapped environments.
[ Contact XPerf ]Autonomous remediation stays within reviewable operator guardrails.
[ See how it works ]Prevent failures, self-heal incidents, and get more from every accelerator.